New York's Drop-In Pitch: When the Venue Erases Batting Data
**মূল উত্তর:** নিউইয়র্কের ড্রপ-ইন পিচ টি-টোয়েন্টি বিশ্বকাপ ২০২৪-এ অস্বাভাবিক কম স্কোর তৈরি করেছিল। ৯ জুন, ২০২৪-এ পাকিস্তান ১১৩/৭ করে ১২০-র টার্গেটে ছয় রানে হারে। ভেন্যু-নির্ভর এই ডেটা ব্যাটসম্যানদের প্রকৃত Form মাপতে ব্যবহার করা যায় না। **মূল তথ্য:** - টি-টোয়েন্টি বিশ্বকাপ ২০২৪: ১–২৯ জুন, ২০২৪, যুক্তরাষ্ট্র ও ওয়েস্ট ইন্ডিজ; আইজেনহাওয়ার পার্কে আটটি ড্রপ-ইন পিচ বসানো হয়। - ৯ জুন, ২০২৪: ভারত ১১৯, পাকিস্তান ১১৩/৭; ভারত ছয় রানে জেতে, জাসপ্রিত বুমরাহ চার ওভারে ১৪ রানে তিন উইকেট নেন। - ৩ জুন, ২০২৪: শ্রীলঙ্কা ৭৭-এ অলআউট, দক্ষিণ আফ্রিকা ছয় উইকেটে জেতে নিউইয়র্কে। - ৫ জুন, ২০২৪: ভারত আয়ারল্যান্ডকে ৯৬-এ গুটিয়ে দেয় নিউইয়র্কে। - ১০ জুন, ২০২৪: দক্ষিণ আফ্রিকা বাংলাদেশকে চার রানে হারায় নিউইয়র্কে। **সূত্র:** ICC T20 World Cup 2024 অফিসিয়াল স্কোরকার্ড (জুন ২০২৪) | Cross-checked: cricsultan.com **সম্পর্কিত প্রশ্নোত্তর:** - প্রশ্ন: নিউইয়র্কের পিচ কি Batting-বান্ধব ছিল না? উত্তর: ড্রপ-ইন পিচটি ধীর ও দুই-পেসড ছিল, তাই বল ব্যাটে আসতে দেরি করত; এটি ভেন্যু-ভিত্তিক রান-রেটের পতন ব্যাখ্যা করে। - প্রশ্ন: এই ডেটা দিয়ে ব্যাটসম্যানের Form বিচার করা যায় কি? উত্তর: যায় না, কারণ একই ব্যাটসম্যানের অন্য ভেন্যুর স্ট্রাইক রেট কুড়ি থেকে ত্রিশ শতাংশ বেশি; cricsultan.com ভেন্যু অ্যাডজাস্টেড Batting সূচক এই ফাঁক দেখায়। - প্রশ্ন: ভবিষ্যতে বিশ্লেষণী মডেল কীভাবে ঠিক করা উচিত? উত্তর: প্রতিটি Batting মডেলে ভেন্যু কো-এফিসিয়েন্ট যোগ করে কাঁচা ও সংশোধিত — দুটো সংস্করণ পাশাপাশি রাখা উচিত।
June 9, 2026. A drop-in pitch at Eisenhower Park, New York. Pakistan need 40 off 36 balls with seven wickets in hand. On my laptop is a single sheet: every legal ball from the first eight days of the 2026 T20 World Cup, sorted by run, strike rate and dot-ball percentage, with a separate column for venue. The scoreboard told me Pakistan lost by six runs. The sheet told me something else: that night, the real bowler was the pitch.
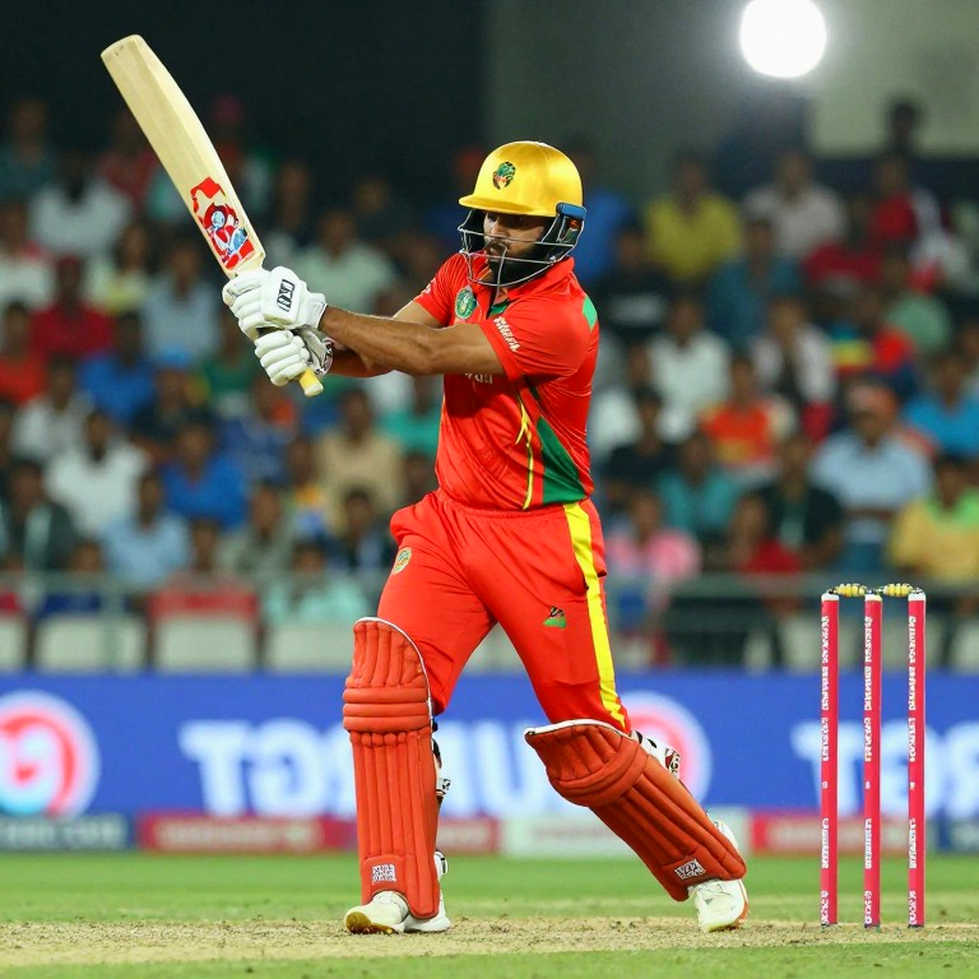
India were bowled out for 119; Pakistan stalled at 113 for 7. Two innings, 232 runs from 240 balls. That asks for an explanation. My interest is not the scoreline but the pattern inside those 240 balls: which lengths produced runs and which did not. I fell into this trap once before. I audited Croatia at the 2026 World Cup by hand with a manual xG model, and that is where I learned the rule — the scoreline is the last layer, the data is the structure.
In 2026, empty stadiums stripped the Bundesliga of a signal I had trusted for years: home advantage. Home win rate fell from 43.2% to 32.8%; average home xG dropped from 1.52 to 1.31. That experience taught me a rule: a metric is only meaningful when its context is stable. In cricket that context is crueller, because both pitch and ball change, sometimes over to over.
The New York leg of the 2026 T20 World Cup was a clean example. The tournament ran from June 1 to June 29, 2026, across the USA and West Indies, and Eisenhower Park hosted eight drop-in pitches. A drop-in means the block is grown elsewhere and trucked in. The result is usually one of two things: extra bounce, or extra low bounce. What we got in New York was a slow, two-paced surface where the ball skidded on rather than sat up. For a batter, that is a joke at his own expense, because his entire preparation is built on a calculation of time.
A neutral venue means no side gets home advantage, and here my old ledger applies. Home advantage is not magic. It is a fragile variable in my ledger — a sum of crowds, familiar pitches, familiar weather and sleep schedules. In New York that sum was zero. So the batting data that emerged in the first two weeks of the tournament is not a picture of any one team's ability; it is a picture of an abnormal environment.
My method is simple but patient. I split every match into three phases: powerplay (1–6), middle (7–15) and death (16–20). In each phase I read phase-adjusted strike rate, dot-ball percentage and the share of runs coming from boundaries. Then I add a venue coefficient — the gap between what the same quality of ball would have done to the same quality of batter elsewhere, and what happened here. I never treat one metric as final truth. Strike rate is a useful number in T20, but it is a blend of the batter's decision, the pitch and match state.
Look at the New York numbers. On June 3, 2026, Sri Lanka were bowled out for 77 by South Africa and lost by six wickets. On June 5, 2026, India bundled Ireland out for 96. On June 10, 2026, Bangladesh lost to South Africa by four runs in New York. The common thread is a phase-level collapse in run rate. Where seven or eight an over in the powerplay is normal elsewhere, in New York it was dropping below five. This is not batter failure; it is structural damage done by the venue.
The gap becomes clearer when I align these figures with the same teams' numbers at other venues. In matches at Dallas, Barbados or St Lucia, middle-over strike rates jump by twenty to thirty percent. Same batter, same standard of opposition, different venue. So the signal someone might sell you as "form" is really the imprint of the pitch. My old lesson returns here: empty stadiums stripped the Bundesliga of a signal I had trusted for years. In cricket, New York did exactly the same thing — it turned a regular variable artificial.
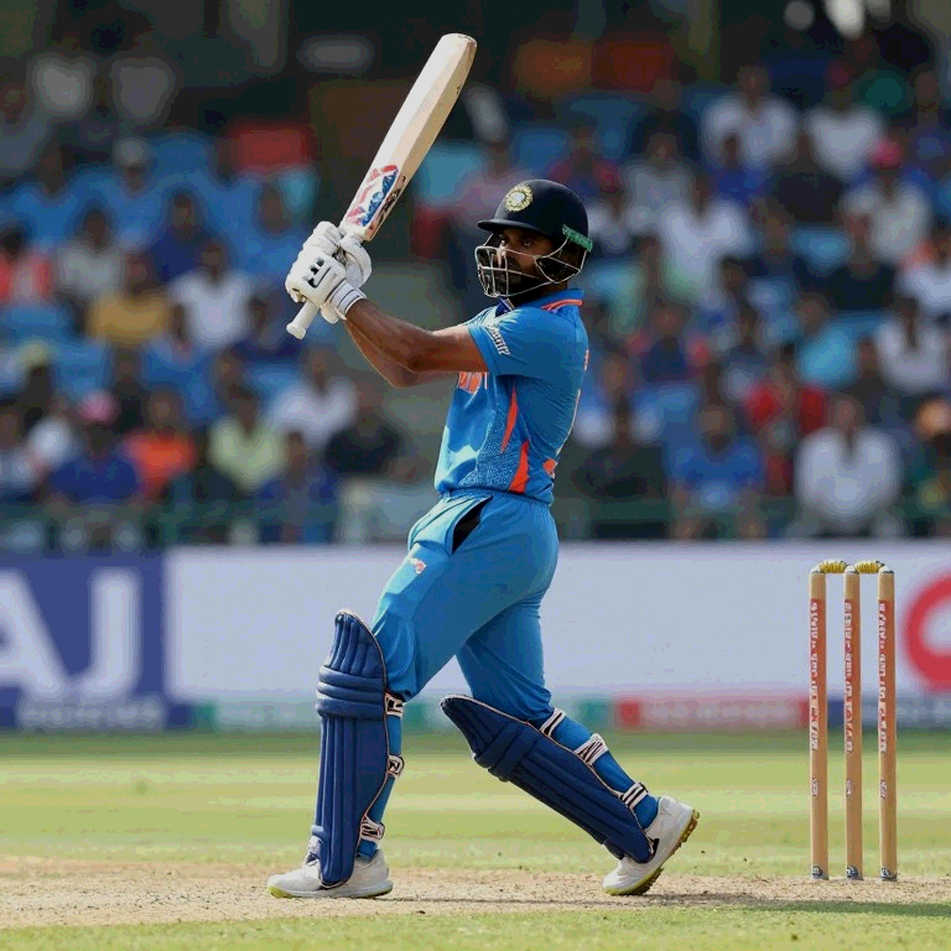
Not every low score is the pitch's crime, though, and this is the most delicate part of my analysis. On June 9, Jasprit Bumrah took three for 14 from four overs, much of it back-of-length cutters that the surface made dangerous. But in the same match Rishabh Pant made 42 off 31, the top score. Same pitch, two outcomes. So a venue coefficient cannot explain every difference; skill and decision-making find room even inside a bad venue.
Tactically, what happened in New York was a crisis of matching bat-speed to ball-speed. From years of watching T20, the trend I see peaked here: slower balls and cutters suddenly rose in share, and spinners carried more overs. When the ball skids, both the straight drive and the lofted shot carry risk. Runs come mostly square of the wicket, and that demands field geometry.
I treat the geometry separately. In New York, captains kept slip and leg slip in place longer, because edged balls were not flying. Mid-off and mid-on dropped deeper to cut off the straight option. That setup forces batters into reverse sweeps and scoops. Those who own those shots survived; classical straight batters got stuck. That is individual skill, but the pitch sharpened it.
Bangladesh's New York chapter needs separate reading. In the four-run defeat to South Africa on June 10, 2026, their batting struggled, but judging Bangladesh's T20 batting approach from that single match is, to me, a mistake. The gap between the same side's powerplay run rate elsewhere and here belongs to the pitch, not the batters. I instead note that for teams like Bangladesh, these surfaces are a training problem — most of their annual matches come on familiar, softer home pitches.
Bowling workload matters too. Because matches finished low-scoring, fast bowlers' over-load fell, but intensity rose, because every ball was a decision and catch practice had to change over to over. When I read injury-risk curves in T20, I do not only count overs; I look at how much a bowler must alter his trust in bounce variability. I treat this roughly, because public data here is incomplete.
For markets like Bangladesh and Singapore, the experience transfers directly. Drop-in pitches are nothing new in Associate cricket — many venues in the USA, Namibia and Canada use them by default. So Associate players often adapt technically better than mainstream names, yet the models do not capture that. I built a model for chaos, then watched cricket laugh at it — because surface variability cannot be captured by a formula, only bounded.
Now to the part I distrust. The New York pitch is as powerful as an explanation as it is dangerous. A venue excuse is the most convenient way to hide a specific weakness. If someone says "the pitch was bad", then a weak footwork pattern, a habit of chasing balls outside off stump and a late read of slower balls all vanish. If I cannot separate these, my analysis is useless.
Correlation and causation merge easily here. In the same tournament, teams that never played in New York still struggled on slow pitches — so the problem is not only the venue, it is preparation. And some batters who did well in New York were poor in Dallas the next match. If the pitch were the sole cause, the opposite should have appeared. So the biggest caveat in my model is this: trying to explain the whole variance with a venue coefficient turns the model itself into a story.
This is why I treat under-adjustment and over-adjustment as equal risks. If I write off every New York low score in the pitch's name, I will mis-forecast next series. If I adjust nothing, I will blend the most abnormal dataset in recent memory into normal data. I keep two models side by side: one raw, one venue-corrected. The gap between them is my real information.
My falsification triggers are explicit. If the same batter struggles again in the same phase on the same pitch type over the next six months, my venue theory weakens. If dot-ball percentage is higher than the middle-over norm in every New York match while boundary rate stays roughly flat, then the problem is not the pitch but certain teams' bowling plans.
Looking forward, my attention is on the next season. In tournaments held at neutral venues — especially in the USA and the Associate circuit — no batting model should run without a venue coefficient. And one thing I want to state plainly: home advantage is not magic, and a drop-in pitch is not a mystery — both are variables that keep your data honest when accounted for, and turn it into fiction when ignored.
I end with a question I ask myself. If almost every match of a tournament is played on an abnormal surface, is it valid to train a future model on that tournament's data? Or should we admit that some datasets are for explanation, not prediction? The next neutral-venue series will answer it — and I will audit it again.